All categories Paiton (40) Artificial Intelligence (28) AMD (13) AMD Radeon (12) vLLM (10) Local AI (9) NVidia (7) Solutions (7) AI (6) AI Inference (6) H200 (6) MI300X (6) Modular DC (6) Quantization (6) Qwen (6) AI Infrastructure (5) AMD MI300X (5) Inference Optimization (5) Trending (5) MI325x (4) Sovereign AI (4) Agentic AI (3) AMD Instinct (3) B200 (3) Cost Efficiency (3) Generative AI (3) GPU Performance (3) H100 (3) Inference Latency (3) Large Language Models (3) Liquid Cooling (3) Local LLM (3) On-Premise AI (3) ComfyUI (2) Cybersecurity (2) Damage Detection (2) Deepseek (2) Document Processing (2) Eliovp (2) Email Automation (2) Enterprise AI (2) FP8 (2) GDPR (2) GPU (2) High Density (2) HPC (2) Image Generation (2) Invoice Extraction (2) Kernel Tuning (2) Llama 3.1 405B (2) MI355x (2) ModFlex (2) Modular Data Center (2) NVL72 (2) Privacy (2) Ticket Automation (2) Workflow Automation (2) 1-2MW Data Center (1) 14B (1) 150kW Rack (1) 3D Generation (1) AI Act (1) AI Agents (1) AI Benchmarks (1) AI Engineering (1) AI Neocloud (1) AI news (1) AI Strategy (1) AMD Helios (1) Anthropomorphism (1) Autonomous Agents (1) AVG (1) AWS (1) Belgian Mobile ID (1) benchmark (1) Benchmarks (1) Benelux (1) Blackwell (1) ChatGPT (1) Circular Financing (1) Cloud Act (1) Cold Start (1) Cold Start Optimization (1) Compute (1) Cost per Token (1) CUDA Translation (1) Data Centers (1) Data Governance (1) Data Security (1) Data Sovereignty (1) De Tijd (1) DeepSeek (1) DFlash2 (1) Diffusion (1) Digital Identity (1) DLC (1) eIDAS (1) ERP (1) FLUX (1) GGUF (1) GPU Cloud (1) GPU Optimization (1) Graph Compilation (1) Hardware (1) Healthcare (1) High Performance Computing (1) High Throughput (1) HIP (1) import (1) Inference (1) Instinct (1) Investment Risks (1) itsme (1) Jim Greene (1) Liberty Global (1) LLM (1) LLM Optimization (1) MI300 (1) Microsoft Copilot (1) MiniMax H3 (1) Mixture of Experts (1) Model Fine-Tuning (1) Model Serving (1) MoE (1) MyGov.be (1) NVIDIA (1) NVIDIA B200 (1) NVIDIA Blackwell (1) NVIDIA Blackwell Ultra (1) NVIDIA GB300 (1) NVIDIA H200 (1) NVIDIA NVL (1) On-Premise (1) Optimization (1) pnl calculator (1) Podcast (1) Precision Cooling (1) Qwen3 (1) Qwen3.8 (1) Rapid Deployment (1) ROCm (1) RX7900XTX (1) SGLang (1) Shadow AI (1) Startup Latency (1) Startup Valuation (1) Synthetic Bubble (1) T2V (1) Taiwan (1) Tariffs (1) Tech Analysis (1) Tech Talk (1) Tensor Parallelism (1) tenstorrent (1) Text-to-Video (1) Trump (1) Tuning (1) Vaporware (1) Venture Capital (1) Vera Rubin (1) Video Generation (1) Video-Generation (1) vLLM Optimization (1) VRAM Optimization (1) Wan2.2 (1)
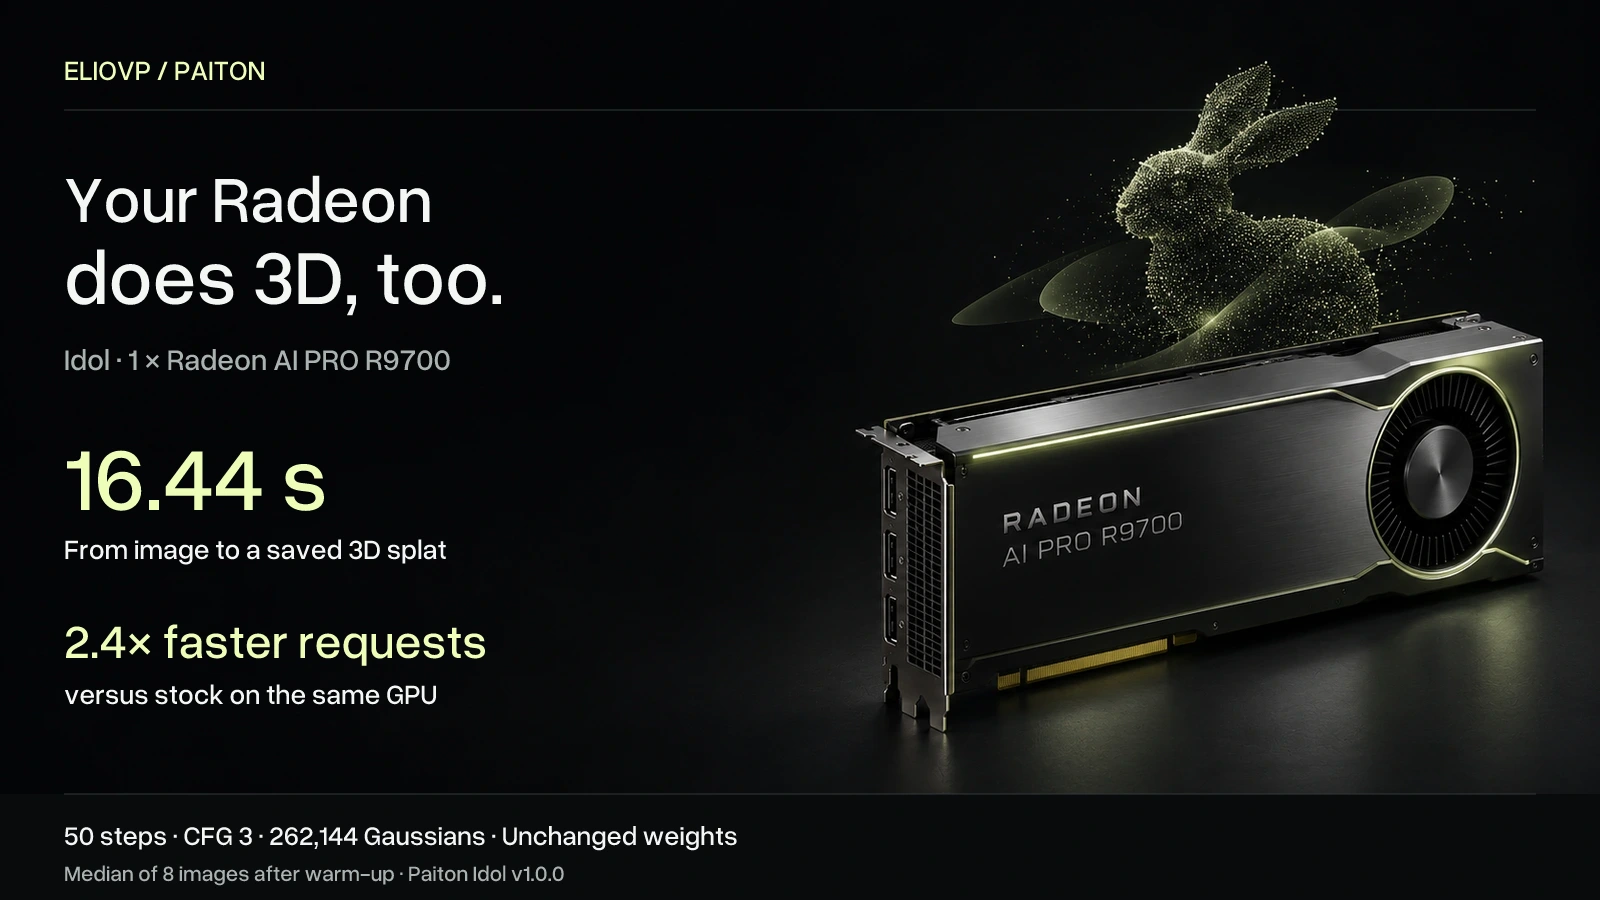
The Radeon AI PRO R9700 does 3D too: Idol in 16.4 seconds Idol turns an image into a 3D Gaussian splat in 16.44 seconds on one Radeon AI PRO R9700 with Paiton, versus 39.22 seconds for stock on the same GPU.
By: ElioVP
November 6, 2026
Paiton
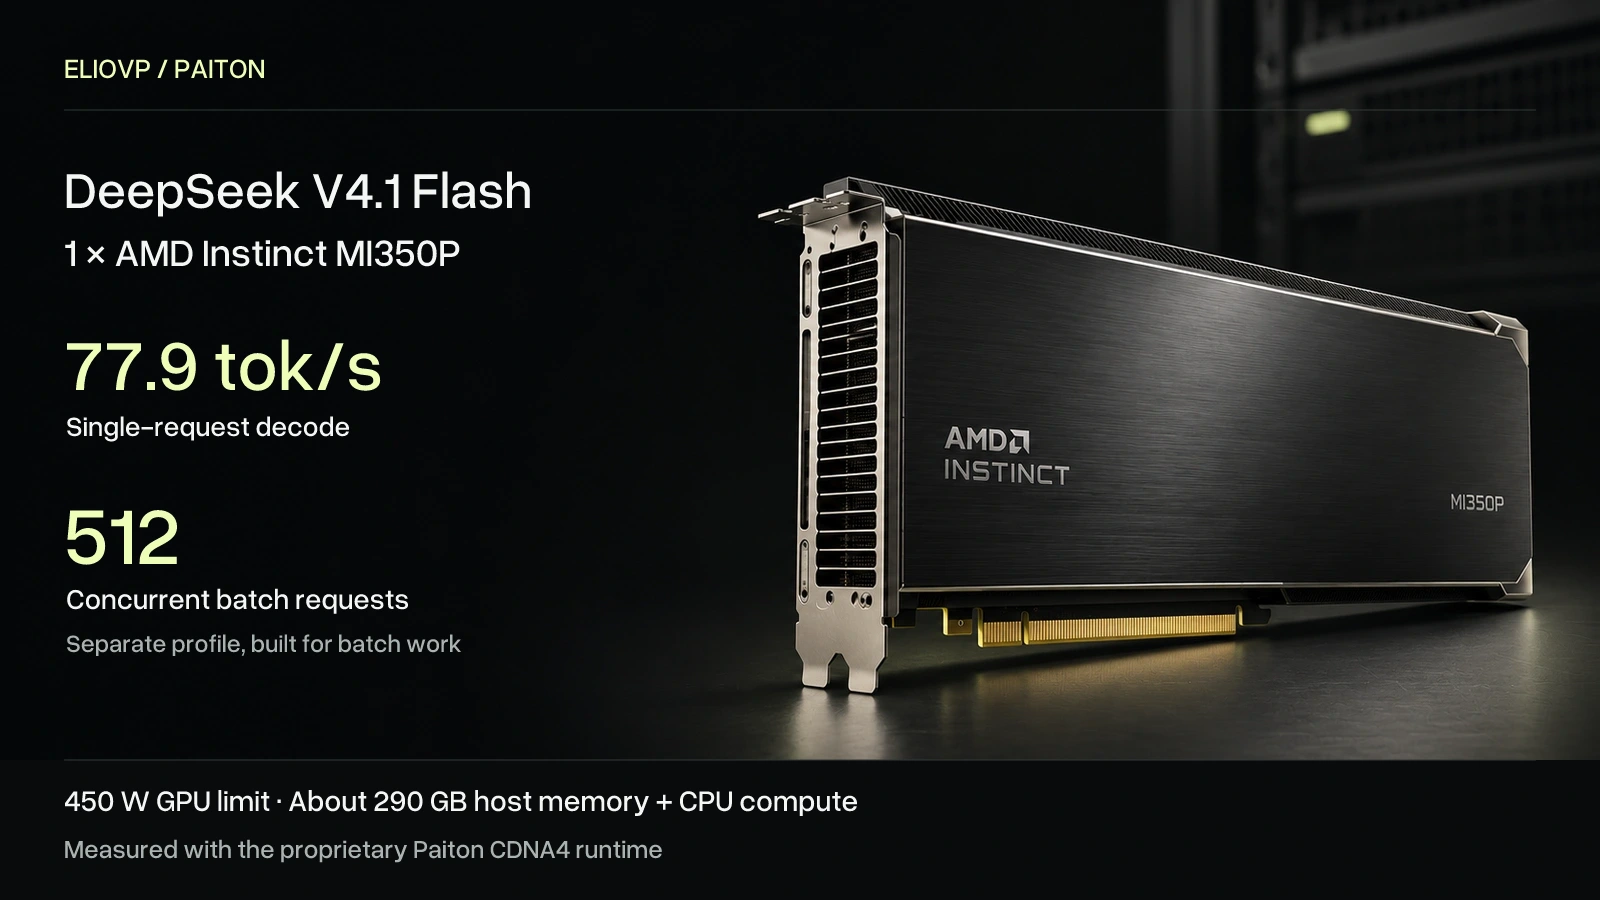
Deepseek V4.1 Flash on a single MI350P DeepSeek V4.1 Flash on one 144 GB MI350P: 77.9 tokens/s for one request and 1,107.6 in a 512-request batch, with Paiton and CPU expert offload.
By: ElioVP
November 3, 2026
Paiton
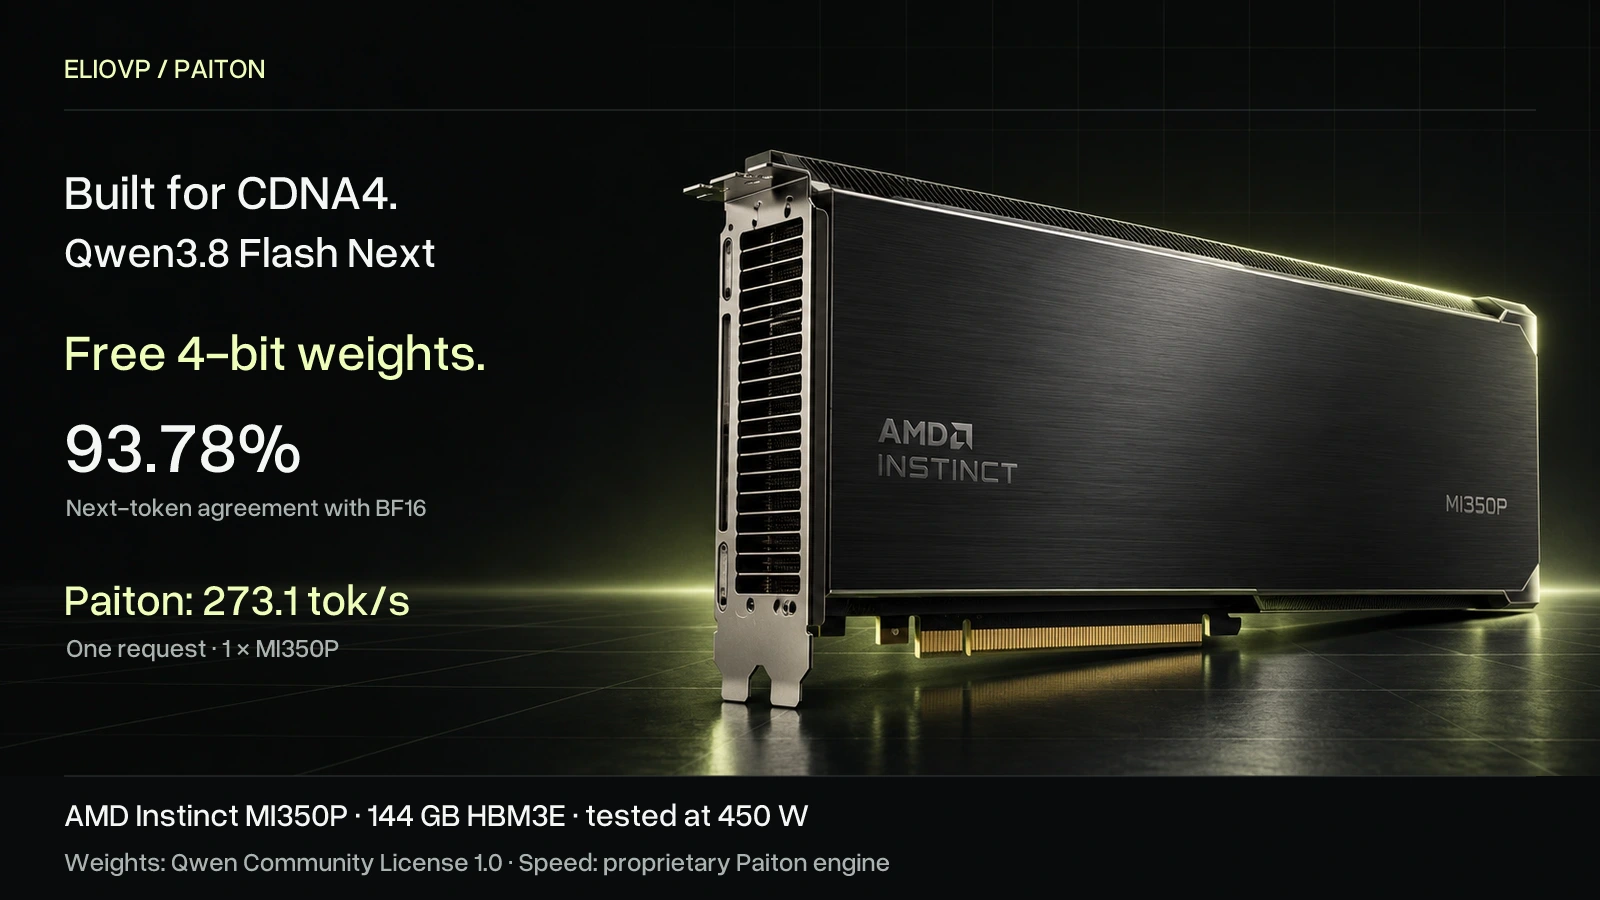
Qwen3.8 Flash Next on MI350P: twice the speed | Paiton Qwen3.8 Flash Next on one AMD MI350P: 2.24× the tested vLLM setup's single-request decode speed and about 2.2 million shared KV-cache tokens with Paiton.
By: ElioVP
October 30, 2026
Paiton
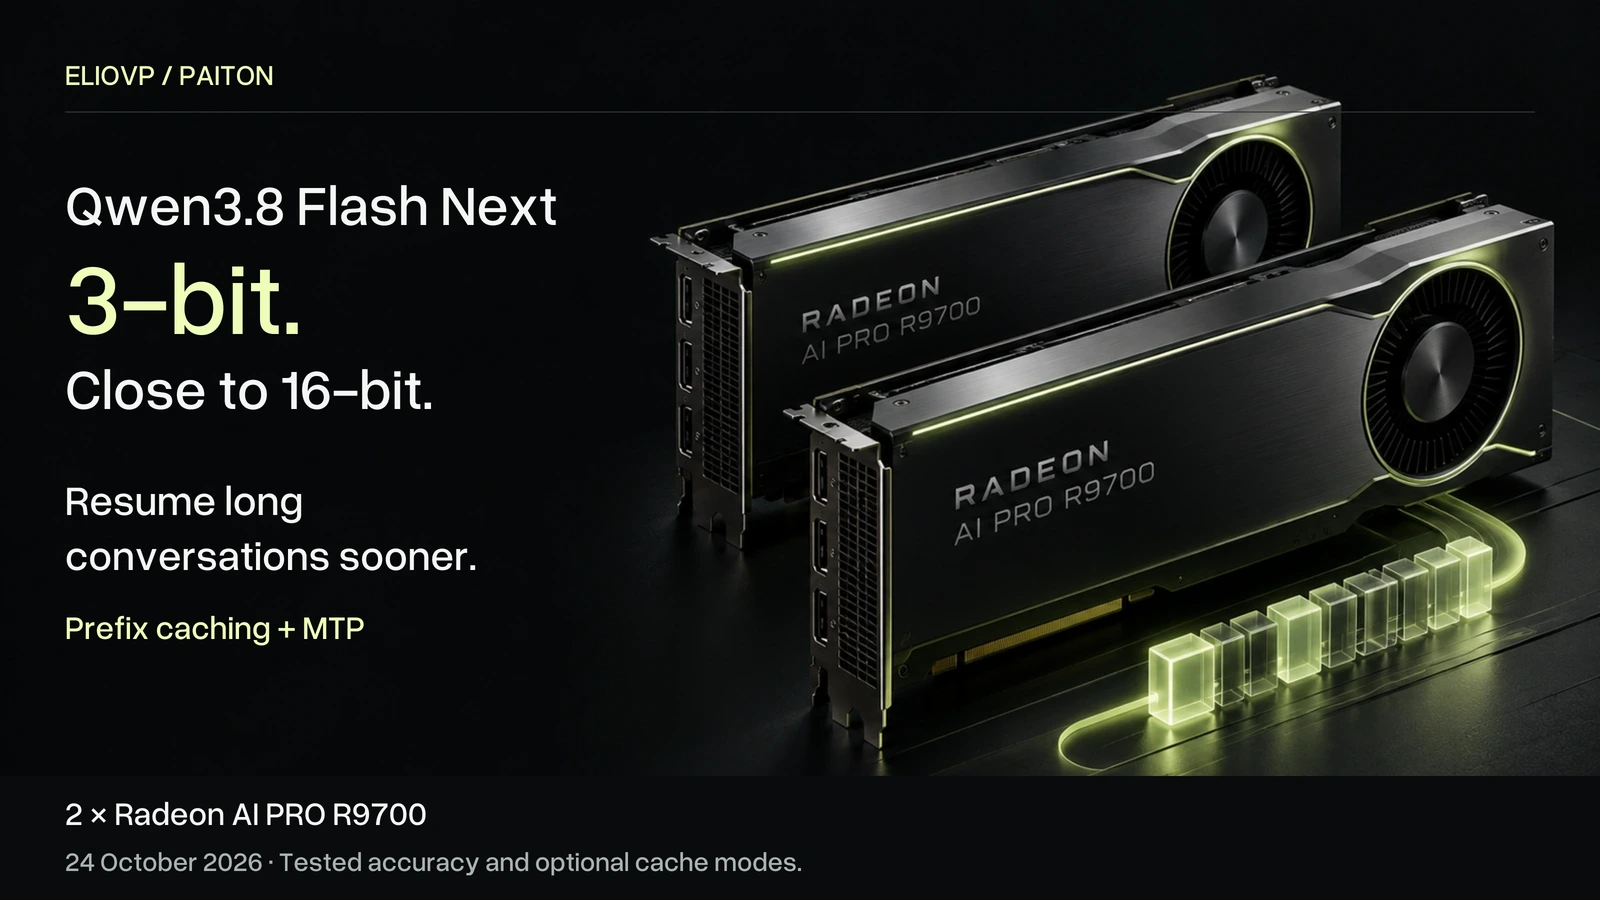
Qwen3.8 Flash Next: 3-bit near 16-bit accuracy, with MTP prefix caching Paiton's new Qwen3.8 3-bit weights approach 16-bit task scores on two R9700 cards. Native MTP prefix caching resumes a 200K prompt in 0.68 seconds. Results, limits and setup.
By: ElioVP
October 24, 2026
Paiton
Nvidia confirms the modular DC direction NVIDIA DSX POD brings Vera Rubin AI factories to modular data centers. ElioVP explains site readiness, cooling and the thinking behind ModFlex.
By: ElioVP
October 21, 2026
Modular DC